Agent Architecture
How I Write Agent Instructions That Actually Work
The structure, rules, and testing habits I use when I help makers write instructions for Copilot Studio agents, including what changed after five rounds on a finance agent.
By Kaustubh Giri, Sr Solution Engineer. ~12 min read.
The question I get most from makers isn’t about connectors or licensing. It’s “Why does my agent do something different every time?” In my experience, the answer is almost always in the instructions.
Instructions are where the agent decides which tool or knowledge source to call, how to fill that tool’s inputs, and how to word the response. Microsoft Learn describes those three jobs explicitly. Vague instructions give you vague behavior in all three places. This post covers how I structure instructions today: a one-line purpose, an orchestrator that routes to skills, a short set of core rules, cost discipline, and a testing loop. I’ll also walk through how instructions for a file-processing finance agent changed over five iterations, because that’s where I learned the most.
A quick caveat: Copilot Studio now has more than one harness. The standard harness uses topics, tools, and generative orchestration. The GitHub Copilot harness adds agent skills and usage-based billing that starts when you begin building. The principles below apply to both, but some features (like skills) are harness-specific. Check current docs for the harness your agent uses.
In this post:
- Start with a one-line purpose
- Orchestrator + skills
- Routing tables
- Core rules that apply everywhere
- Cost discipline
- Deterministic file-processing agents
- An annotated skeleton
- Testing, versioning, and comparing runs
- Anti-patterns I see often
1. Start with a one-line purpose
Before any rules or steps, I write one sentence that says who the agent serves and what outcome it produces. Not what it “can help with”. The outcome.
| Weak | Strong |
|---|---|
| “You are a helpful sales assistant that can research companies and write emails.” | “Help one business consultant book net-new first meetings with employers of 20 to 150 employees in one state.” |
| “This agent helps with finance tasks.” | “Process the attached bank report, keep only the rows that match the sweep condition, and produce an import-ready journal entry file.” |
Why it matters: every later decision gets measured against that line. When the agent is unsure whether to research one more company or stop, a precise purpose answers the question.
2. Orchestrator + skills: core instructions route, skills hold procedures
The most common failure I see is a single block of instructions that tries to describe every procedure the agent might ever run. It becomes long, rules start contradicting each other, and the agent blends steps from different tasks.
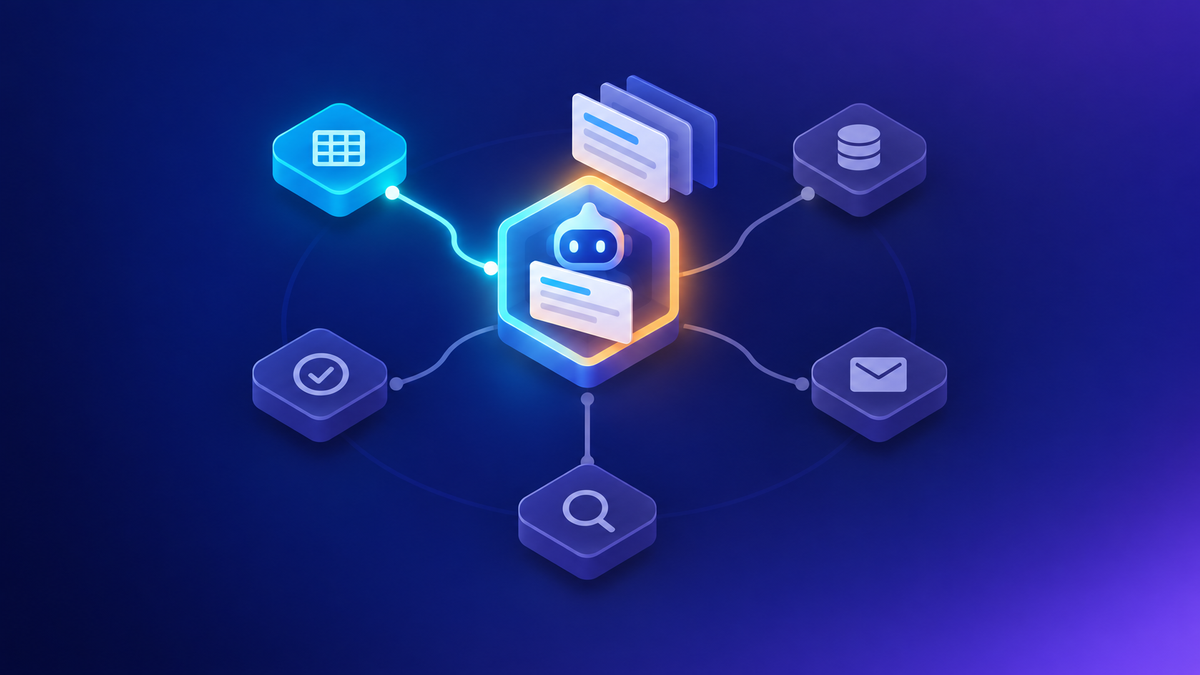
Here’s how I approach it now. The core instructions act as an orchestrator. They classify the request, pick the right skill, run skills in order, and return the result. The detailed procedures live in skills, one per job. In the GitHub Copilot harness, skills are packages with a name, a description, and Markdown instructions. They use progressive disclosure, so the agent loads a skill’s full content only when it needs it. Microsoft’s guidance for declarative agents makes the same point from the other side: refer to skills at a high level in the instructions instead of duplicating their steps.
- Core instructions (Route and enforce) - Purpose, routing table, core rules, cost discipline, output contract. Short and stable.
- Skills (Hold the procedure) - Step-by-step workflow, inputs, outputs, edge cases for one job. Changed independently.
- Tools & knowledge (Do the work) - Connectors, MCP servers, flows, and documents. Described well so the orchestrator picks them correctly.
The orchestrator I shared recently with a customer opens with a short “how to work” list. I’d recommend something close to it for any multi-skill agent:
- Classify the request using the routing table.
- Load only the skills the request needs, then follow the skill exactly. Don’t work from general knowledge when a skill covers the task.
- For multi-step requests, chain skills in the listed order and pass results forward. Don’t repeat a step whose output is already in the conversation.
- If no skill fits, answer briefly under the core rules.
- Return only what the skill’s output section specifies.
3. Routing tables
A routing table is the cheapest reliability improvement I know. It maps the words users actually type to the skill, or chain of skills, that should run. The agent still uses tool and skill descriptions to decide, but the table removes ambiguity where two skills overlap.
| Request signals | Skill(s), in order |
|---|---|
| Research, evaluate a company, who to contact | account-research |
| Email, phone, direct dial, “find contact info” | contact-resolution |
| Score, rank, prioritize | prospect-scoring (after account-research if no evidence yet) |
| Write an email, follow-up, voicemail script | outreach-writing |
| Put it in Outlook, create a draft, send | email-execution |
| “Research X and write the email” | account-research -> contact-resolution -> outreach-writing -> stop |
Two details matter. First, list signals in the user’s vocabulary, not yours. Second, end chains with an explicit “stop”. Without it, an agent asked to write an email will often helpfully go on to draft it in Outlook.
From the field: A business consultant at a professional employer organization had built a prospecting agent with one long instruction block. It worked, but it was slow and expensive, and it would sometimes enrich contacts nobody asked about. We rebuilt it as an orchestrator with a routing table and seven small skills. My follow-up to him was deliberately ordered: first confirm the new agent produces the right outcome, then look at credit consumption. Measuring cost on an agent that’s doing the wrong thing tells you very little.
4. Core rules that apply everywhere
Core rules sit in the orchestrator and apply inside every skill. I keep the list short, and each rule is there because I’ve seen the failure it prevents.
| Rule | Why I include it |
|---|---|
| Never invent data. | Models fill gaps fluently. A plausible but invented phone number is worse than none. |
| Label unknowns. Use fixed labels such as Unknown, User-supplied, unverified, and Business hypothesis. | The reader can see what is fact, what is the user’s claim, and what is inference. If you score things, unknowns score zero. |
| Word results by what the source returned. “No direct dial was retrieved”, never “none exists”. | The agent only knows what its tools returned. It should also never claim to have searched a source it didn’t search. |
| Ask before any write action. | Drafts, sends, CRM or Dataverse updates, meetings, and paid lookups all need explicit approval. Approval for one paid source doesn’t cover another. |
| “Draft” is not “send”. | The single most common complaint I hear about email agents. Spell it out. |
This lines up with Microsoft’s guidance on control layers: anything mission-critical or irreversible should be handled deterministically rather than left to the model’s judgment. Instructions are the soft layer. For true write actions, I also restrict what the tool itself can do.
5. Cost discipline
Copilot Credits are the unit for agent usage, and Microsoft is clear that consumption depends on how the agent is designed, not just how often it’s used. In the standard harness, features such as generative answers and tool calls have their own billing rates. In the GitHub Copilot harness, credits cover LLM tokens, tools (including knowledge and MCP), and the harness itself, and billing starts while you build and test. Either way, every unnecessary skill load or repeated lookup costs something. I put a short cost section right in the core instructions:
- Load the fewest skills needed. Never load one “just in case”.
- Reuse retrieved facts. If company size is already in the conversation, don’t look it up again.
- Don’t call the same source twice for the same entity.
- Check free sources before paid ones. Internal data first, paid enrichment last and only with approval.
- Stop after one systematic failure. If a tool fails on authentication or schema, retrying ten times just burns credits.
- Keep answers short. No methodology or reasoning unless the user asks.
My tip: Before you write cost rules, use the Copilot Studio agent usage estimator and the agent’s Monitor page to see where credits actually go. For admin-level tracking across environments, see the capacity section of my governance toolbox post.
6. Deterministic file-processing agents
Conversational agents tolerate some variation. File-processing agents don’t. When an education company’s finance team asked for an agent that reads a daily bank report in Excel, keeps only rows of one transaction type, writes records to Dataverse, and produces a CSV for their accounting system import, “close enough” meant a failed import.
We went through five versions of the instructions in a single working session. Each change came from something we saw in a real run.
Versions 1-2: Make it explicit
- Filter on a named column with an exact text match
- Write only to the listed Dataverse tables
- Full CSV column list, in order
- Constants and a lookup table for account codes
- Unmapped value: don’t guess, flag and report
Versions 3-4: Scope and deliver
- Export only records created in this run, never older rows
- Check debits equal credits per transaction
- Save the file to a named OneDrive folder
- Verify the share link works before reporting success
- Retry once, then report the failure clearly
Version 5: Reorder and validate
- Compute lines in memory first
- Build and deliver the CSV before any Dataverse write
- Never output the CSV as chat text
- Exact column count, line endings, quoting rules
- Re-parse the file before upload
What each lesson looks like as an instruction:
- Columns: name the source column and the exact match value. Give the output columns as an ordered list and say which are constants, which are mapped, and that everything else stays blank.
- Validation: every row has the same number of fields as the header. Blank means empty, never “null” or “N/A”. Quote any field containing a comma.
- Output format: one file, a fixed naming pattern with the date, UTF-8, straight quotes, consistent line endings.
- Delivery location: a named folder, plus a confirmed working link. Never say the file was created without checking.
- Nothing matches: say so, and create no file and no records. Silence or an empty file is the worst outcome for a finance user.
From the field: Two surprises shaped version 5. First, the agent reported that it had saved a file when it had only reformatted text in its reply. That’s why “confirm the link resolves” became a rule. Second, users were copying CSV text from chat into a text editor, which broke line endings, dropped commas, and swapped in smart quotes. The import failed even though the data was right. Moving file creation before the Dataverse writes also meant a Dataverse error could no longer block the file the team actually needed.
I’d temper expectations here. Instructions made this agent far more consistent, but a language model following instructions is still not a parser. Microsoft’s guidance says that if something must happen exactly as specified, handle it deterministically. Once the procedure stabilized, we packaged it as a reusable skill. For production, I’d recommend moving the CSV build and validation into a flow or script the agent calls, and keeping the instructions for orchestration and error reporting.
7. An annotated skeleton
Here’s a generic skeleton I start from, written for a fictional facilities-request agent. Swap in your own purpose, skills, and rules.
| Instruction text | Why it’s there |
|---|---|
# PurposeHelp site managers log and track facilities requests until each one has an owner and a due date. |
One line. Names the user and the outcome. |
# How to work1. Classify the request with the routing table. 2. Load only the skills needed and follow them exactly. 3. Chain skills in order; don’t repeat a step already done in this conversation. 4. If no skill fits, answer briefly. |
Makes the core instructions an orchestrator. Numbered because order matters. |
# Routing“new issue”, “broken”, “report” -> log-request“status”, “where is my ticket” -> check-status“assign”, “who owns” -> assign-owner (ask first) |
User vocabulary on the left, skill names on the right. |
# Core rulesNever invent request IDs, owners, or dates. Say “Unknown” when a value wasn’t returned. Describe results by what the tool returned. Ask before creating, updating, or assigning anything. Drafting a message is not sending it. |
Applies inside every skill. Each rule maps to a failure seen in testing. |
# Cost disciplineLoad the fewest skills. Reuse facts already retrieved. Don’t call the same tool twice for the same request. Stop a tool after one systematic failure. Keep answers short. |
Keeps credit use proportional to the task. |
# OutputReturn a table: Request ID, Location, Status, Owner, Due date. One sentence of next steps. Nothing else. |
A fixed output contract makes runs comparable. |
# When nothing matchesSay no matching requests were found and offer to log a new one. |
Defines the empty case so the agent doesn’t improvise. |
8. Testing, versioning, and comparing runs
Instructions are code. Microsoft’s own guidance says the system treats them similarly, and that when complex instructions stop working you should remove them and add them back one at a time, testing between each addition. I’d add three habits.
Test with real files and real phrasing
For the finance agent, the real bank export had extra header rows and inconsistent descriptions that no sample file did. Use real (or properly masked) files, and write test prompts the way users actually type them.
Version the instructions
Keep each version as a separate, numbered copy with a one-line change note, outside the agent itself. When version 4 regresses, you want to diff it against version 3, not reconstruct it from memory.
Compare runs against the same test set
Copilot Studio’s agent evaluation lets you build a test set and rerun it after each change, so you have an objective baseline. A single-response test set holds up to 100 test cases, and methods include exact match, keyword match, compare meaning, and tool use. For file agents, I also compare outputs directly: same input file, same expected row count, same column count, same totals.
Watch out: Evaluation results are kept in Copilot Studio for 89 days, so export them to CSV if you want a longer history. In the GitHub Copilot harness, generating and running evaluations also consumes credits. Budget for testing.
9. Anti-patterns I see often
- The everything prompt. Every procedure in one block. Split into an orchestrator and skills.
- Listing every tool in the instructions. The agent already knows its tools. Microsoft recommends naming tools only where the choice is ambiguous, and using the exact tool name when you do.
- Instructions for tools the agent doesn’t have. An agent can’t follow “search the FAQ” unless the FAQ is configured as knowledge.
- Fighting the platform. Instructions can’t change retrieval logic, the fallback message, or citation behavior. Trying to suppress or reformat citations can actually cause answers to be dropped.
- Vague words. “Process the file properly” or “the typing box”. Name columns, values, and formats.
- Undefined edge cases. No rule for empty results, unmapped values, or tool failures. The agent will improvise, differently each time.
- Silent writes. Any create, update, or send without a confirmation step.
- Measuring cost before quality. Fix the behavior first, then optimize credits.
Where I’d start
Take your current agent and write its purpose in one sentence. If you can’t, that’s the first fix. Then move procedures into skills (or clearly separated sections, if your harness doesn’t support skills yet), add a routing table and the five core rules, and add a short cost section. Build a small test set from real inputs before you change anything else, and number every version. For file-processing agents, be explicit about columns, validation, output format, delivery location, and the empty case. And plan to move the strictly deterministic parts into a flow or script. If you’re also setting up environments for these agents, my environment strategy and DLP post covers where they should live.
Happy to go deeper on any of this.
K.G.
Sources
- Microsoft Learn: Write agent instructions (Copilot Studio)
- Microsoft Learn: Configure high-quality instructions for generative orchestration
- Microsoft Learn: Apply generative orchestration capabilities
- Microsoft Learn: Configure agent details and instructions (GitHub Copilot); Skills overview for agents (GitHub Copilot)
- Microsoft Learn: Write effective instructions for declarative agents
- Microsoft Learn: Billing rates and management; Overview of usage-based billing (GitHub Copilot harness)
- Microsoft Learn: About agent evaluation; Create a single response test set; Run evaluations and view results
Product details reflect publicly available information as of October 2026. Preview features may change. Customer examples are anonymized, and the instruction skeleton is a generic illustration, not a customer’s text.

Get new posts by email
Provider: your email provider